
Start with the right question
Most teams do not choose a database because a benchmark says it is faster. They decide based on when data must be visible, who needs to ask questions, how often records change, and how they want to manage cost.
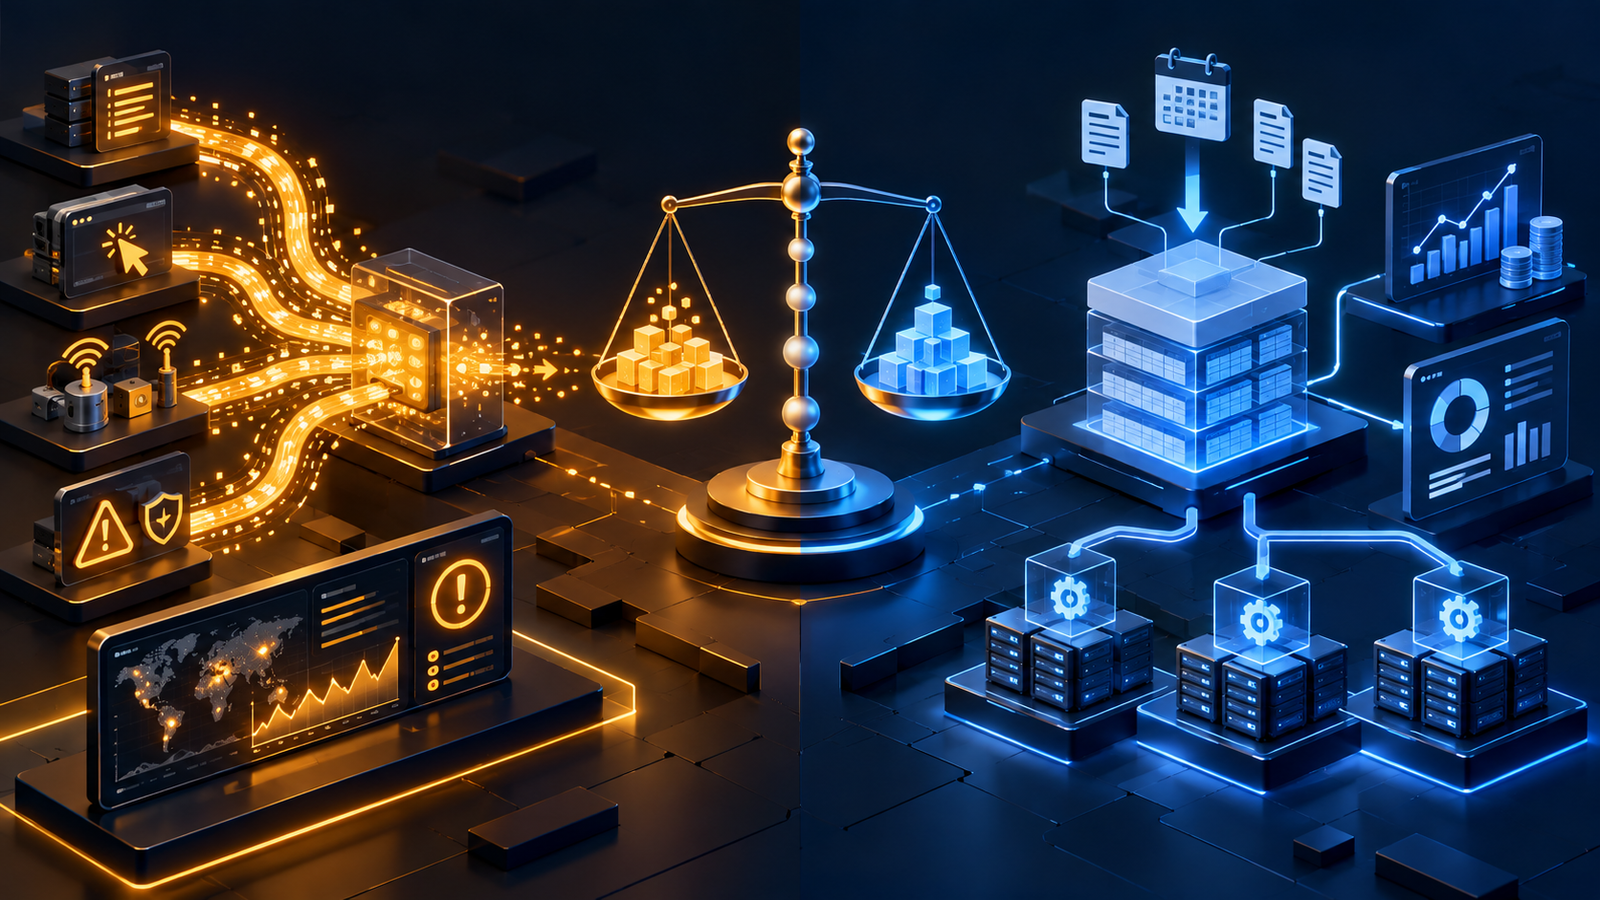
The decision is workload-led
Both are powerful analytical platforms. The right choice depends less on a feature checklist and more on freshness, query pattern, operational model, governance, and cost behaviour.
ClickHouse
Best evaluated when data arrives continuously and users, APIs, or dashboards need fresh aggregations with low latency. Its table engines and sort order are central to performance.
Snowflake
Best evaluated when teams want a managed cloud warehouse with separated compute, broad SQL workloads, data sharing, and governance across many users and business domains.
Architecture in practical terms
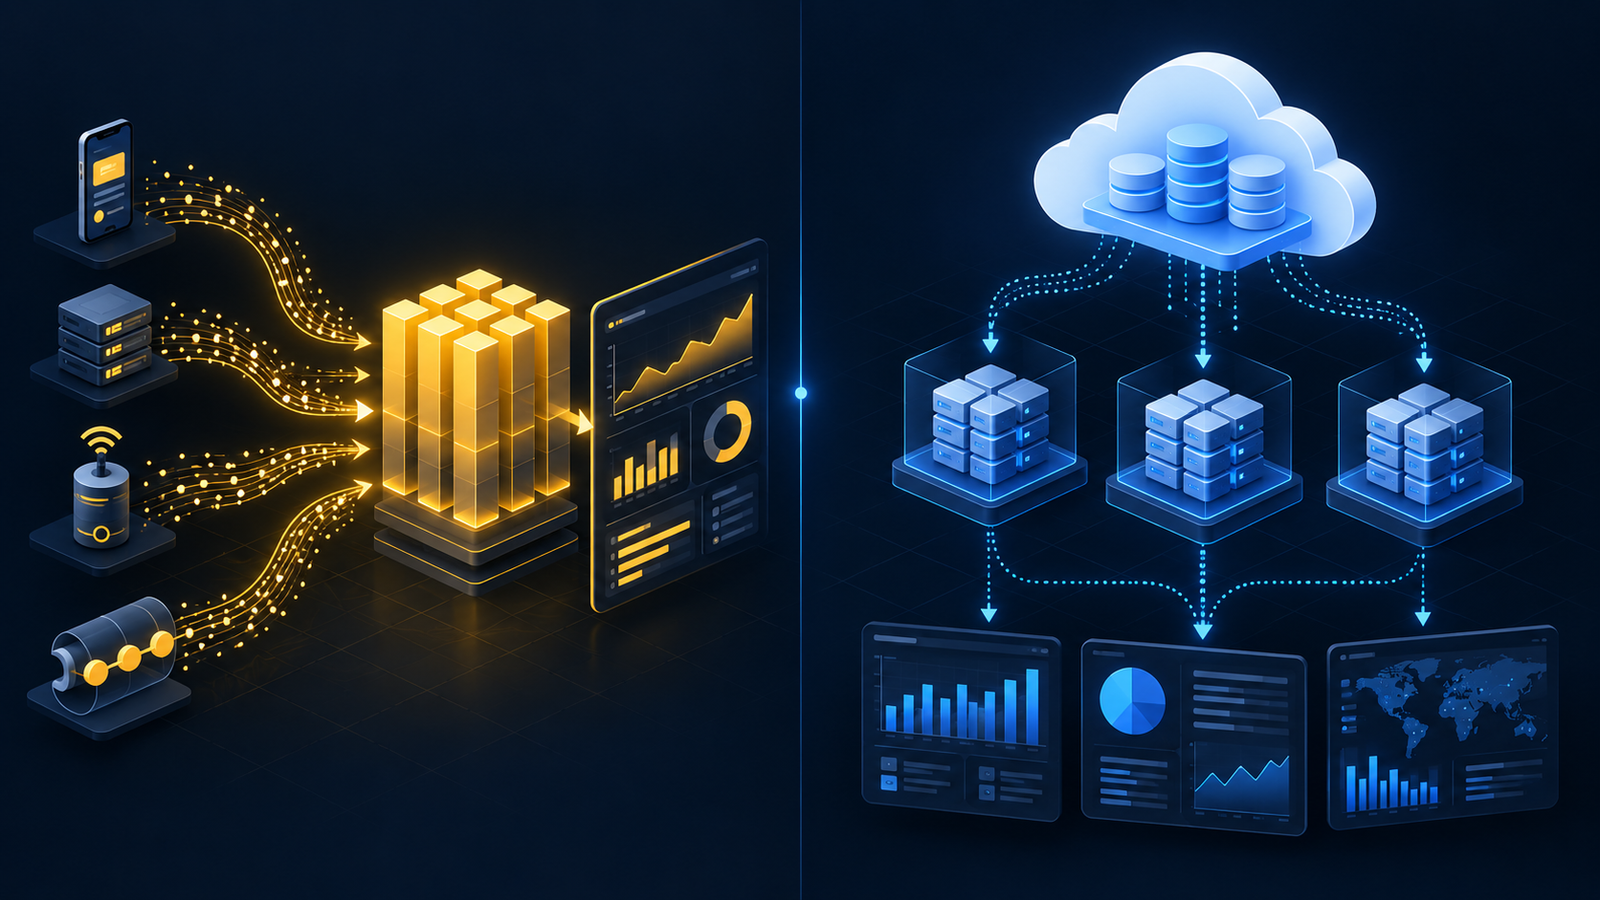
Animated data flow: sources → analytics platform → dashboards
The animated dotted lines show continuous data movement. The colours represent workload patterns only; they do not imply a vendor recommendation.
| Dimension | ClickHouse | Snowflake |
|---|---|---|
| Core model | Columnar analytical database built for high-throughput ingestion and low-latency analytics. | Cloud data platform with independently managed storage and virtual-warehouse compute. |
| Physical design | Engine, partition key, and especially ORDER BY are deliberate design choices. | Automatic micro-partitions. Clustering keys are optional optimizations for large, selective workloads. |
| Freshness pattern | Commonly used for event streams, logs, metrics, and operational analytics in milliseconds to seconds. | Strong for batch and near-real-time analytics. Snowpipe Streaming can provide low latency ingestion, but the full path must be measured. |
| Compute isolation | Depends on deployment and resource configuration. Cloud simplifies operations, while self-managed clusters need capacity planning. | Virtual warehouses isolate workloads, which improves team separation but can increase credit use. |
| Update model | Optimized for inserts. Updates and deletes use mutations, lightweight operations, or versioned-insert patterns depending on the use case. | Supports familiar INSERT, UPDATE, DELETE, and MERGE warehouse workflows. |
How query execution differs
ClickHouse: design for data skipping
Most ClickHouse analytical tables use the MergeTree family. Data is stored in immutable parts, ordered on disk by the table’s ORDER BY expression. The primary index is sparse: it helps ClickHouse skip granules rather than locate one individual row like an OLTP B-tree index.
Filtering on leading sort-key dimensions can be dramatically more efficient than filtering on an unrelated column. Partitions are mainly a data-management boundary; they are not a substitute for a good sort key.
Snowflake: design for micro-partition pruning
Snowflake stores data in automatically created micro-partitions and records metadata that helps eliminate unnecessary partitions and columns at query time. Users usually do not declare partitions up front.
Natural load order often provides useful pruning. When a very large table is repeatedly filtered on dimensions that do not align with natural clustering, a clustering key may help—but its maintenance consumes credits and can increase storage turnover.
ClickHouse question
Which columns dominate dashboard filters, range scans, and groupings?
Snowflake question
Which workloads need their own warehouse, and when should it suspend?
Both platforms
How much data does a representative query scan, and what is its freshness target?
Ingestion and CDC: the important difference
ClickHouse is commonly fed by streaming inserts, Kafka-compatible pipelines, object storage, or managed ClickPipes. Its ideal input is often append-heavy event data. For source systems that update rows, teams usually model versions and deletion state explicitly, then expose a current-state view or table.
Snowflake commonly ingests files with COPY INTO or Snowpipe and can use Snowpipe Streaming for low-latency ingestion. It offers warehouse-style transformation patterns after data lands. Do not label either platform “real time” purely because data arrived: measure from the source event, through ingestion and transformation, until the dashboard query returns.
The trade-offs to plan for
ClickHouse operational gaps
- Schema design has consequences. A poor sort key can turn a fast system into one that scans too much data.
- Frequent row-by-row updates are not its natural path. Large mutations rewrite data parts and may run asynchronously. CDC designs often use
ReplacingMergeTreeand versioned rows instead. - Eventual merge behaviour needs understanding. Deduplication or aggregate merges may not be physically complete immediately. Querying with
FINALcan be expensive at scale. - Self-managed operations are real work. Replication, backups, observability, upgrades, Keeper, and capacity management need ownership unless ClickHouse Cloud is used.
Snowflake operational gaps
- Compute cost needs guardrails. Warehouses consume credits while running. Auto-suspend, warehouse sizing, and workload separation matter.
- Concurrency may trade performance for spend. Scaling or using multiple warehouses isolates users, but it is not free.
- Clustering is not automatically free. Clustering keys can improve pruning but automatic reclustering consumes credits and can add storage turnover.
- Historical protection has storage implications. Time Travel and Fail-safe retain changed data and therefore affect storage usage.
Real-world scenarios
1. Live product analytics or an in-app dashboard
A consumer application needs to show clicks, purchases, errors, and conversion rate from the last few minutes. The workload is write-heavy, filters by time and dimensions, and needs sub-second aggregates for many dashboard refreshes. ClickHouse is usually the more natural primary analytics store.
2. Logs, metrics, traces, and security events
Engineers investigate incidents by filtering high-cardinality time-series data. They need fresh data, rapid ingestion, and fast drill-down. ClickHouse’s real-time analytics pattern and time-oriented storage make it a strong fit.
3. Finance, BI, and governed enterprise reporting
Finance, sales, operations, and data science need curated models, scheduled transformations, audited access, data sharing, and independent compute for different teams. Snowflake is often the simpler operational choice when the key requirement is a managed enterprise warehouse rather than a customer-facing live analytics backend.
4. Variable, ad-hoc business analysis
An analyst team runs unpredictable, resource-heavy SQL over structured and semi-structured data. Separate virtual warehouses can prevent one team’s workload from blocking another, provided warehouse cost policies are in place.
5. One business, two latency needs
Use ClickHouse for live telemetry, operational dashboards, product analytics, and alerting. Use Snowflake for governed reporting across functions, long-running ELT, and data sharing. Send the same source events to both platforms or aggregate operational data into Snowflake on a controlled schedule. Do not force one database to serve every job.
Updates, deletes, and CDC
| Concern | ClickHouse pattern | Snowflake pattern |
|---|---|---|
| Append-only events | The natural and most efficient pattern. Insert batches or streaming records, then query immediately. | Works well through bulk loads, Snowpipe, or Snowpipe Streaming; choose the ingestion approach based on latency and cost. |
| Row updates from a source database | Often represented by a new version of the row. ReplacingMergeTree, a version column, and a deletion flag are common CDC patterns. | Usually handled with standard MERGE or transformation SQL, which is familiar to warehouse teams. |
| Physical delete / rewrite | Can involve asynchronous background mutations or lightweight delete/update behaviour. Query visibility and performance must be tested under real load. | DML changes micro-partitions. Historical retention and Fail-safe mean changed data can influence storage cost after the SQL statement finishes. |
| Common mistake | Using ClickHouse like MySQL: issuing constant single-row updates and expecting immediate physical replacement. | Using a large always-running warehouse for every workload, then discovering the cost only at month end. |
Cost and performance mistakes to avoid
ClickHouse anti-patterns
- Creating a separate small insert for every event instead of batching appropriately.
- Using
FINALin every dashboard query to compensate for an unplanned CDC model. - Using high-cardinality strings without considering
LowCardinality, codecs, or data types. - Partitioning by a very granular value, creating too many parts.
- Treating a partition key as the only performance choice while ignoring
ORDER BY.
Snowflake anti-patterns
- Leaving warehouses running because auto-suspend is not configured or is too long.
- Scaling warehouses before inspecting query profile, pruning, data model, and result reuse.
- Applying clustering keys to every table instead of only tables with a proven pruning problem.
- Benchmarking only cached queries or only a single concurrent user.
- Ignoring Time Travel, Fail-safe, data transfer, and serverless-service costs in the total cost model.
A practical POC plan
- Select two representative workloads: one live operational query and one governed reporting or ELT query.
- Use production-like data: preserve the real distribution, cardinality, data volume, updates, and late-arriving events.
- Define success metrics: p50/p95 query latency, data freshness, concurrent users, scanned bytes, ingest cost, and failure recovery time.
- Test for several days: include peak periods, backfills, schema changes, update/delete events, and a restart scenario.
- Review cost with usage evidence: never decide from a single fast query or an introductory credit balance.
Example: real-time event analytics in ClickHouse
The sort order places common filter dimensions first. It is an example, not a universal template: choose ORDER BY after looking at your actual filters and grouping patterns.
CREATE TABLE analytics.events
(
  event_time DateTime64(3), event_id UUID, user_id UInt64,
  event_name LowCardinality(String), product String,
  amount Decimal(13, 2), region LowCardinality(String)
)
ENGINE = MergeTree
PARTITION BY toYYYYMM(event_time)
ORDER BY (event_name, event_time, region, user_id);

SELECT toStartOfMinute(event_time) AS minute, count() AS events,
  round(sumIf(amount, event_name = 'purchase'), 2) AS revenue
FROM analytics.events
WHERE event_time >= now() - INTERVAL 15 MINUTE
GROUP BY minute ORDER BY minute;
For CDC data with updates, model “current state” explicitly. A common approach is a versioned ReplacingMergeTree table plus a current-state view; do not assume a standard row update behaves like MySQL.
Example: governed warehouse analysis in Snowflake
The same event shape can live in Snowflake. The example uses a virtual warehouse that can auto-suspend when idle, which is a key cost-control setting.
CREATE WAREHOUSE IF NOT EXISTS BI_WH
  WAREHOUSE_SIZE = 'SMALL'
  AUTO_SUSPEND = 60
  AUTO_RESUME = TRUE;

SELECT DATE_TRUNC('MINUTE', EVENT_TIME) AS MINUTE, COUNT(*) AS EVENTS,
  SUM(IFF(EVENT_NAME = 'purchase', AMOUNT, 0)) AS REVENUE
FROM ANALYTICS.EVENTS
WHERE EVENT_TIME >= DATEADD(MINUTE, -15, CURRENT_TIMESTAMP())
GROUP BY 1 ORDER BY 1;
Decision framework
- Set a freshness target. Do users need data in seconds, minutes, or next-day reporting?
- Measure the query shape. Identify filters, joins, concurrency, scanned data, and target response time.
- Model the write pattern. Append-only events, CDC updates, and frequent transactional changes are different workloads.
- Model the cost pattern. Evaluate ingest, compute, storage, transformation, concurrency, and recovery. Do not decide from a single query benchmark.
- Run a representative POC. Use the same data distribution, concurrency, and failure cases as production.